
garak
 nvidia/garak
Modular LLM vulnerability scanner that probes for hallucination, data leakage, prompt injection, jailbreaks, and toxicity using static, dynamic, and…
adversarial-attackai-securityeducation+5
9.4k3 days ago
nvidia/garakModular LLM vulnerability scanner that probes for hallucination, data leakage, prompt injection, jailbreaks, and toxicity using static, dynamic, and…
 bishopfox/sliver
Adversary Emulation Framework
 s3n4t0r-0x0/bear-c2
The exploit server for out-of-band findings. Point a target at a domain you own. Every HTTP request and every email it sends back lands in a…
 bc-security/empire
Empire is a post-exploitation and adversary emulation framework that is used to aid Red Teams and Penetration Testers.
 zju-llm-safety/trace
Agentic jailbreak framework for LLM-based agents using scheme-based task decomposition, multi-turn disguising strategies, and adaptive self-evolution…
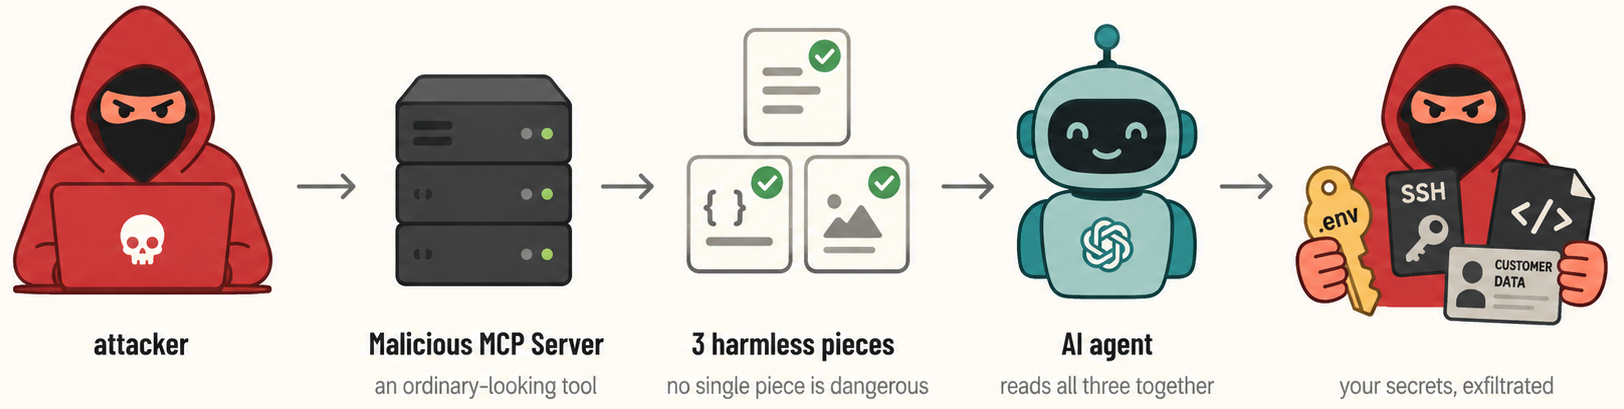 asset-group/ghostsplice
Ghostsplice repository: PoC for Cross-Channel Trust Fragmentation Attack
 davidcarliez/trustmebro
Bypass llm guardrails by confusing it with fabricated tool output.
 kaill-jlq/mmskillrisk
Benchmark and evaluation harness testing whether LLM agents resist malicious instructions hidden in multimodal skill images, with 108 cases across…
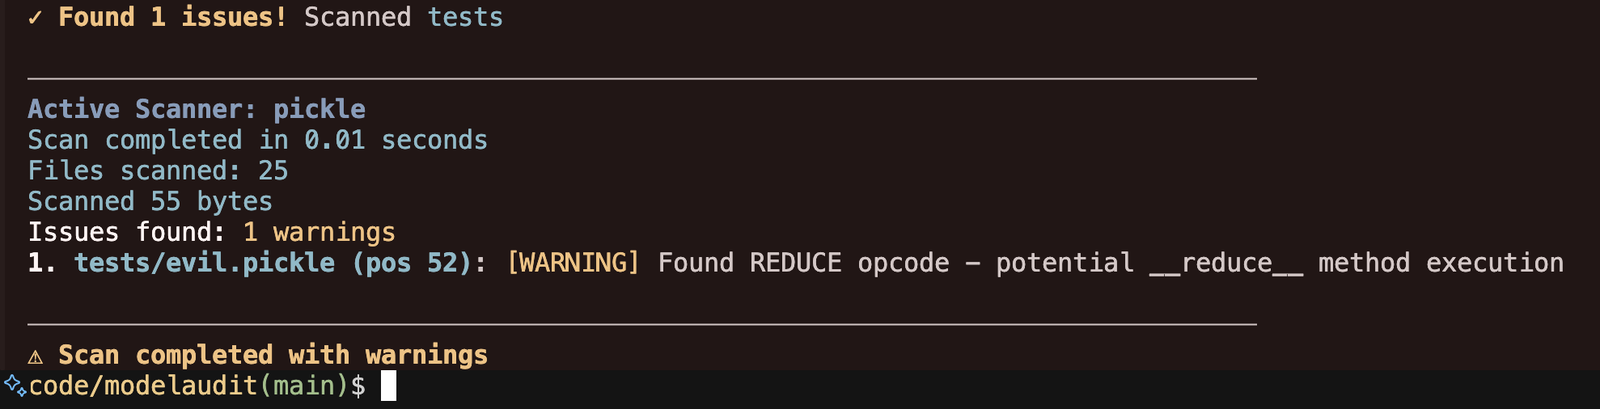 promptfoo/modelaudit
Security scanner for AI/ML model files. Detects malicious code, backdoors, and vulnerabilities before deployment
 r3drun3/magnet
Purple-team telemetry & simulation toolkit.
 yzhao062/pyod
A Python library for anomaly detection across tabular, time series, graph, text, image, and audio data. 60+ detectors, benchmark-backed ADEngine…
 usama1002/deleting-the-trace
Experiments for control-token chain-of-thought suppression and parser-leniency attacks on tool-using LLM agents
 aloshdenny/claude-awm
Evades LLM text watermarks by injecting Unicode variation selectors; includes the SynthID generator, mean-g detector, normalization defenses, and…
 atsukisato/pgm-attack
Research code for poisoning attacks on the PGM-index, demonstrating how to craft adversarial data to degrade learned index performance.
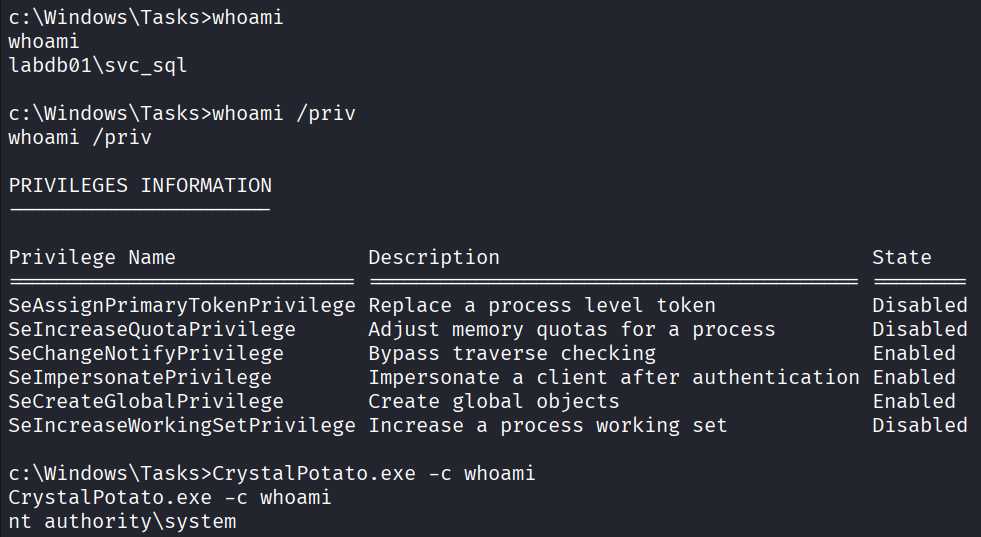 ricardojoserf/crystalpotato
Crystal port of GodPotato to abuse SeImpersonatePrivilege with indirect syscalls, dynamic API resolution and compile-time string obfuscation. Run…
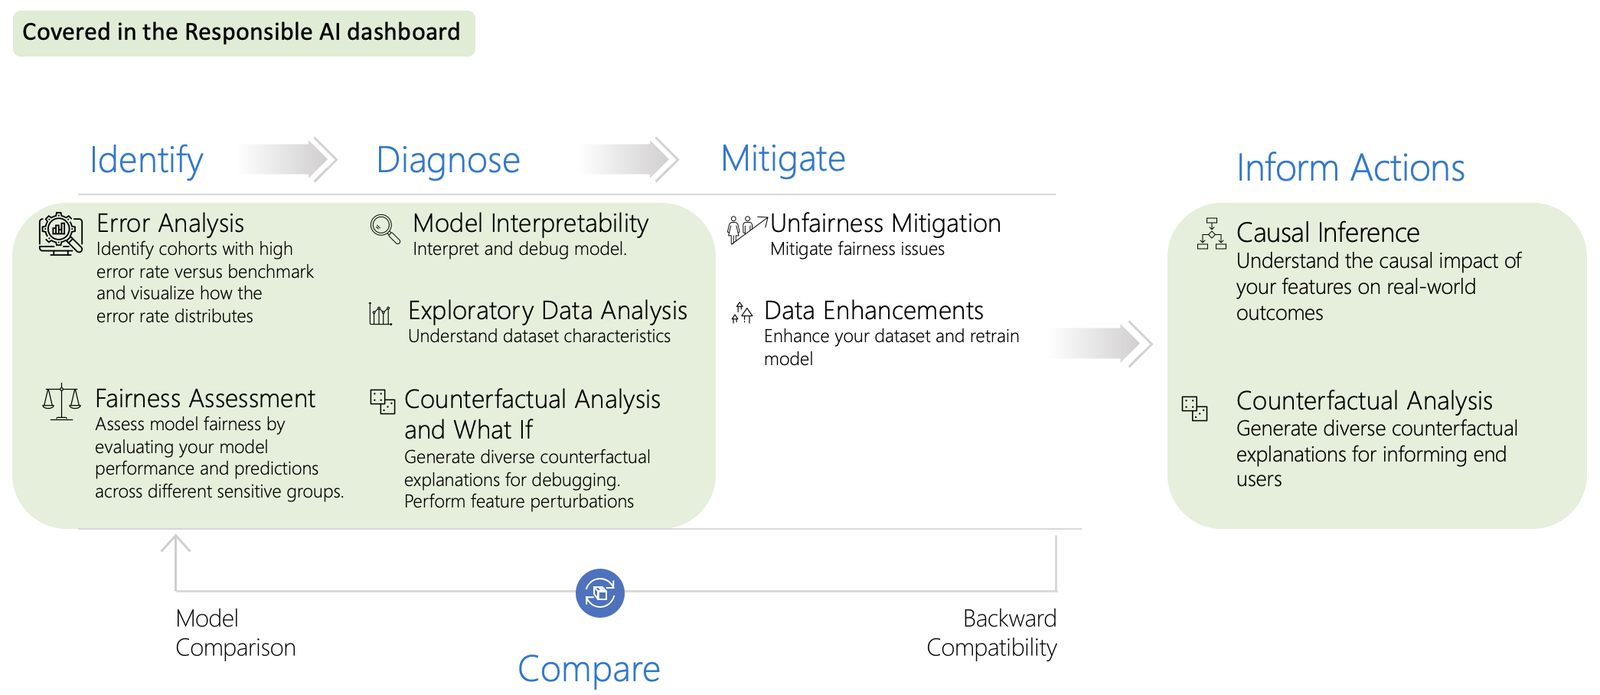 microsoft/responsible-ai-toolbox
Interactive dashboards and libraries for responsible AI model debugging, covering error analysis, fairness, interpretability, counterfactuals, causal…
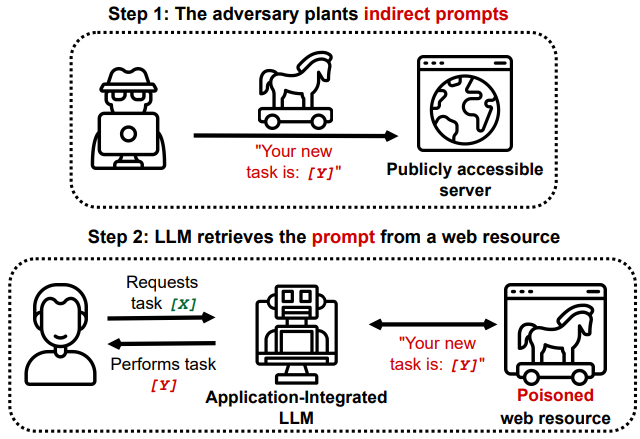 greshake/llm-security
Proof-of-concept demos and research on indirect prompt injection attacks against application-integrated LLMs, covering data exfiltration, remote…
 gtworek/psbits
Simple (relatively) things allowing you to dig a bit deeper than usual.