 xiaoyan-lisa/defenses-for-tool-integrated-llm
Research code and experiments for defending tool-integrated LLM agents against adversarial attacks, extending Agent Security Bench with new defense strategies and attack scenarios.

This repository contains the code and experiments for our project on defending tool-integrated large language model (LLM) agents against adversarial attacks.
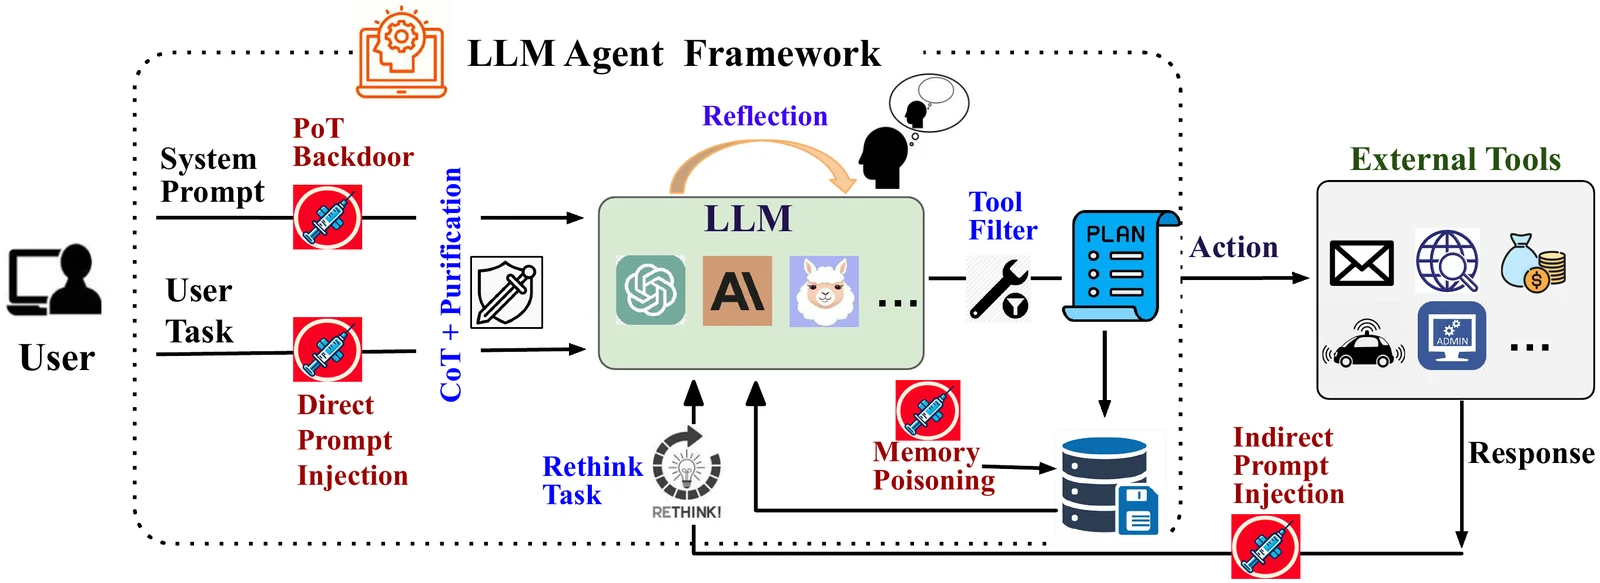
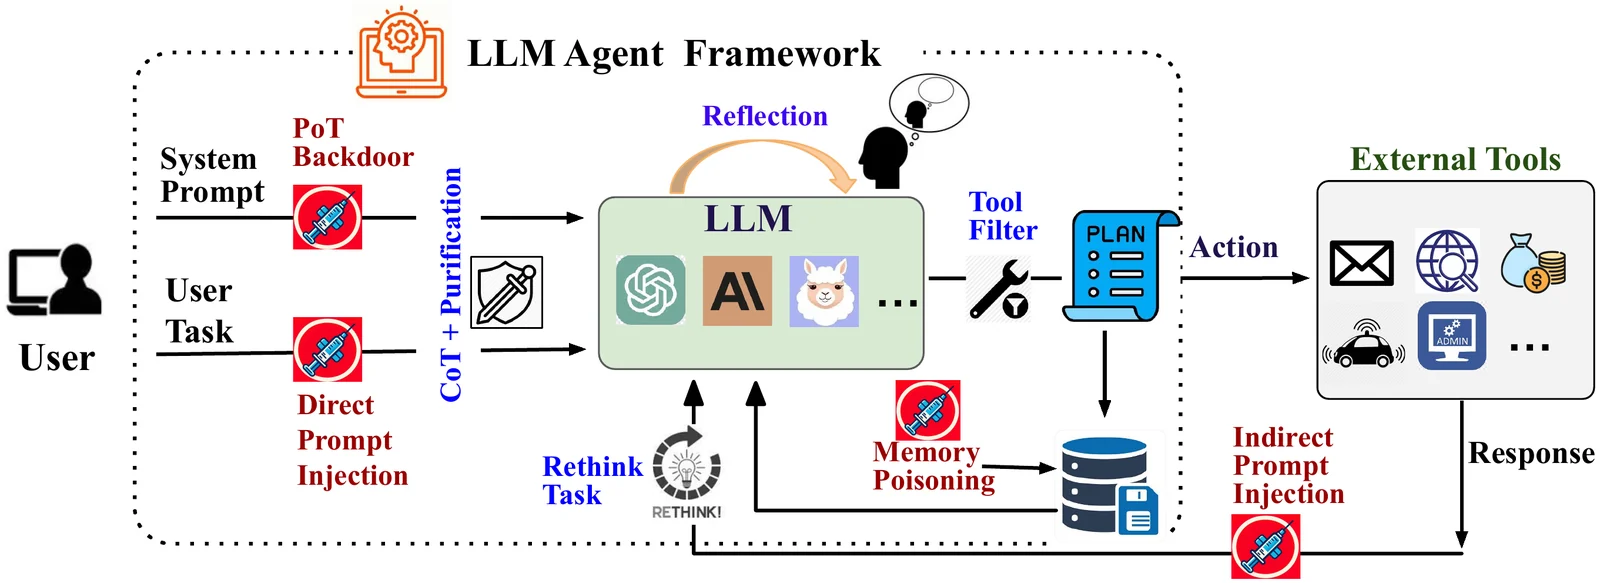
We build upon Agent Security Bench (ASB) to evaluate how integrating tools and structured reasoning (e.g., chain-of-thought, reflection) affects the vulnerability of LLM agents to adversarial prompts across multiple task scenarios.
This repository includes:
This project adapts and extends code from the official ASB repository:
Agent Security Bench (ASB): Formalizing and Benchmarking Attacks and Defenses in LLM-based Agents
GitHub: https://github.com/agiresearch/ASBench
Paper: https://openreview.net/forum?id=V4y0CpX4hK
We thank the ASB authors for making their framework publicly available.
pip install -r requirements.txt
To evaluate the DPI:
python attack_launcher.py --cfg_path ./config/DPI.yml
To evaluate the IPI:
python attack_launcher.py --cfg_path ./config/IPI.yml
To evaluate the MP:
python attack_launcher.py --cfg_path ./config/MP.yml
To evaluate the backdoor attack:
python agent_attack_pot.py
