 suraj-ranganath/stealthrl
StealthRL: RL framework for adversarially paraphrasing AI text to stress-test detector robustness.

Paper (arXiv)
Demo
Model (Hugging Face)
Benchmark Dataset (Hugging Face)
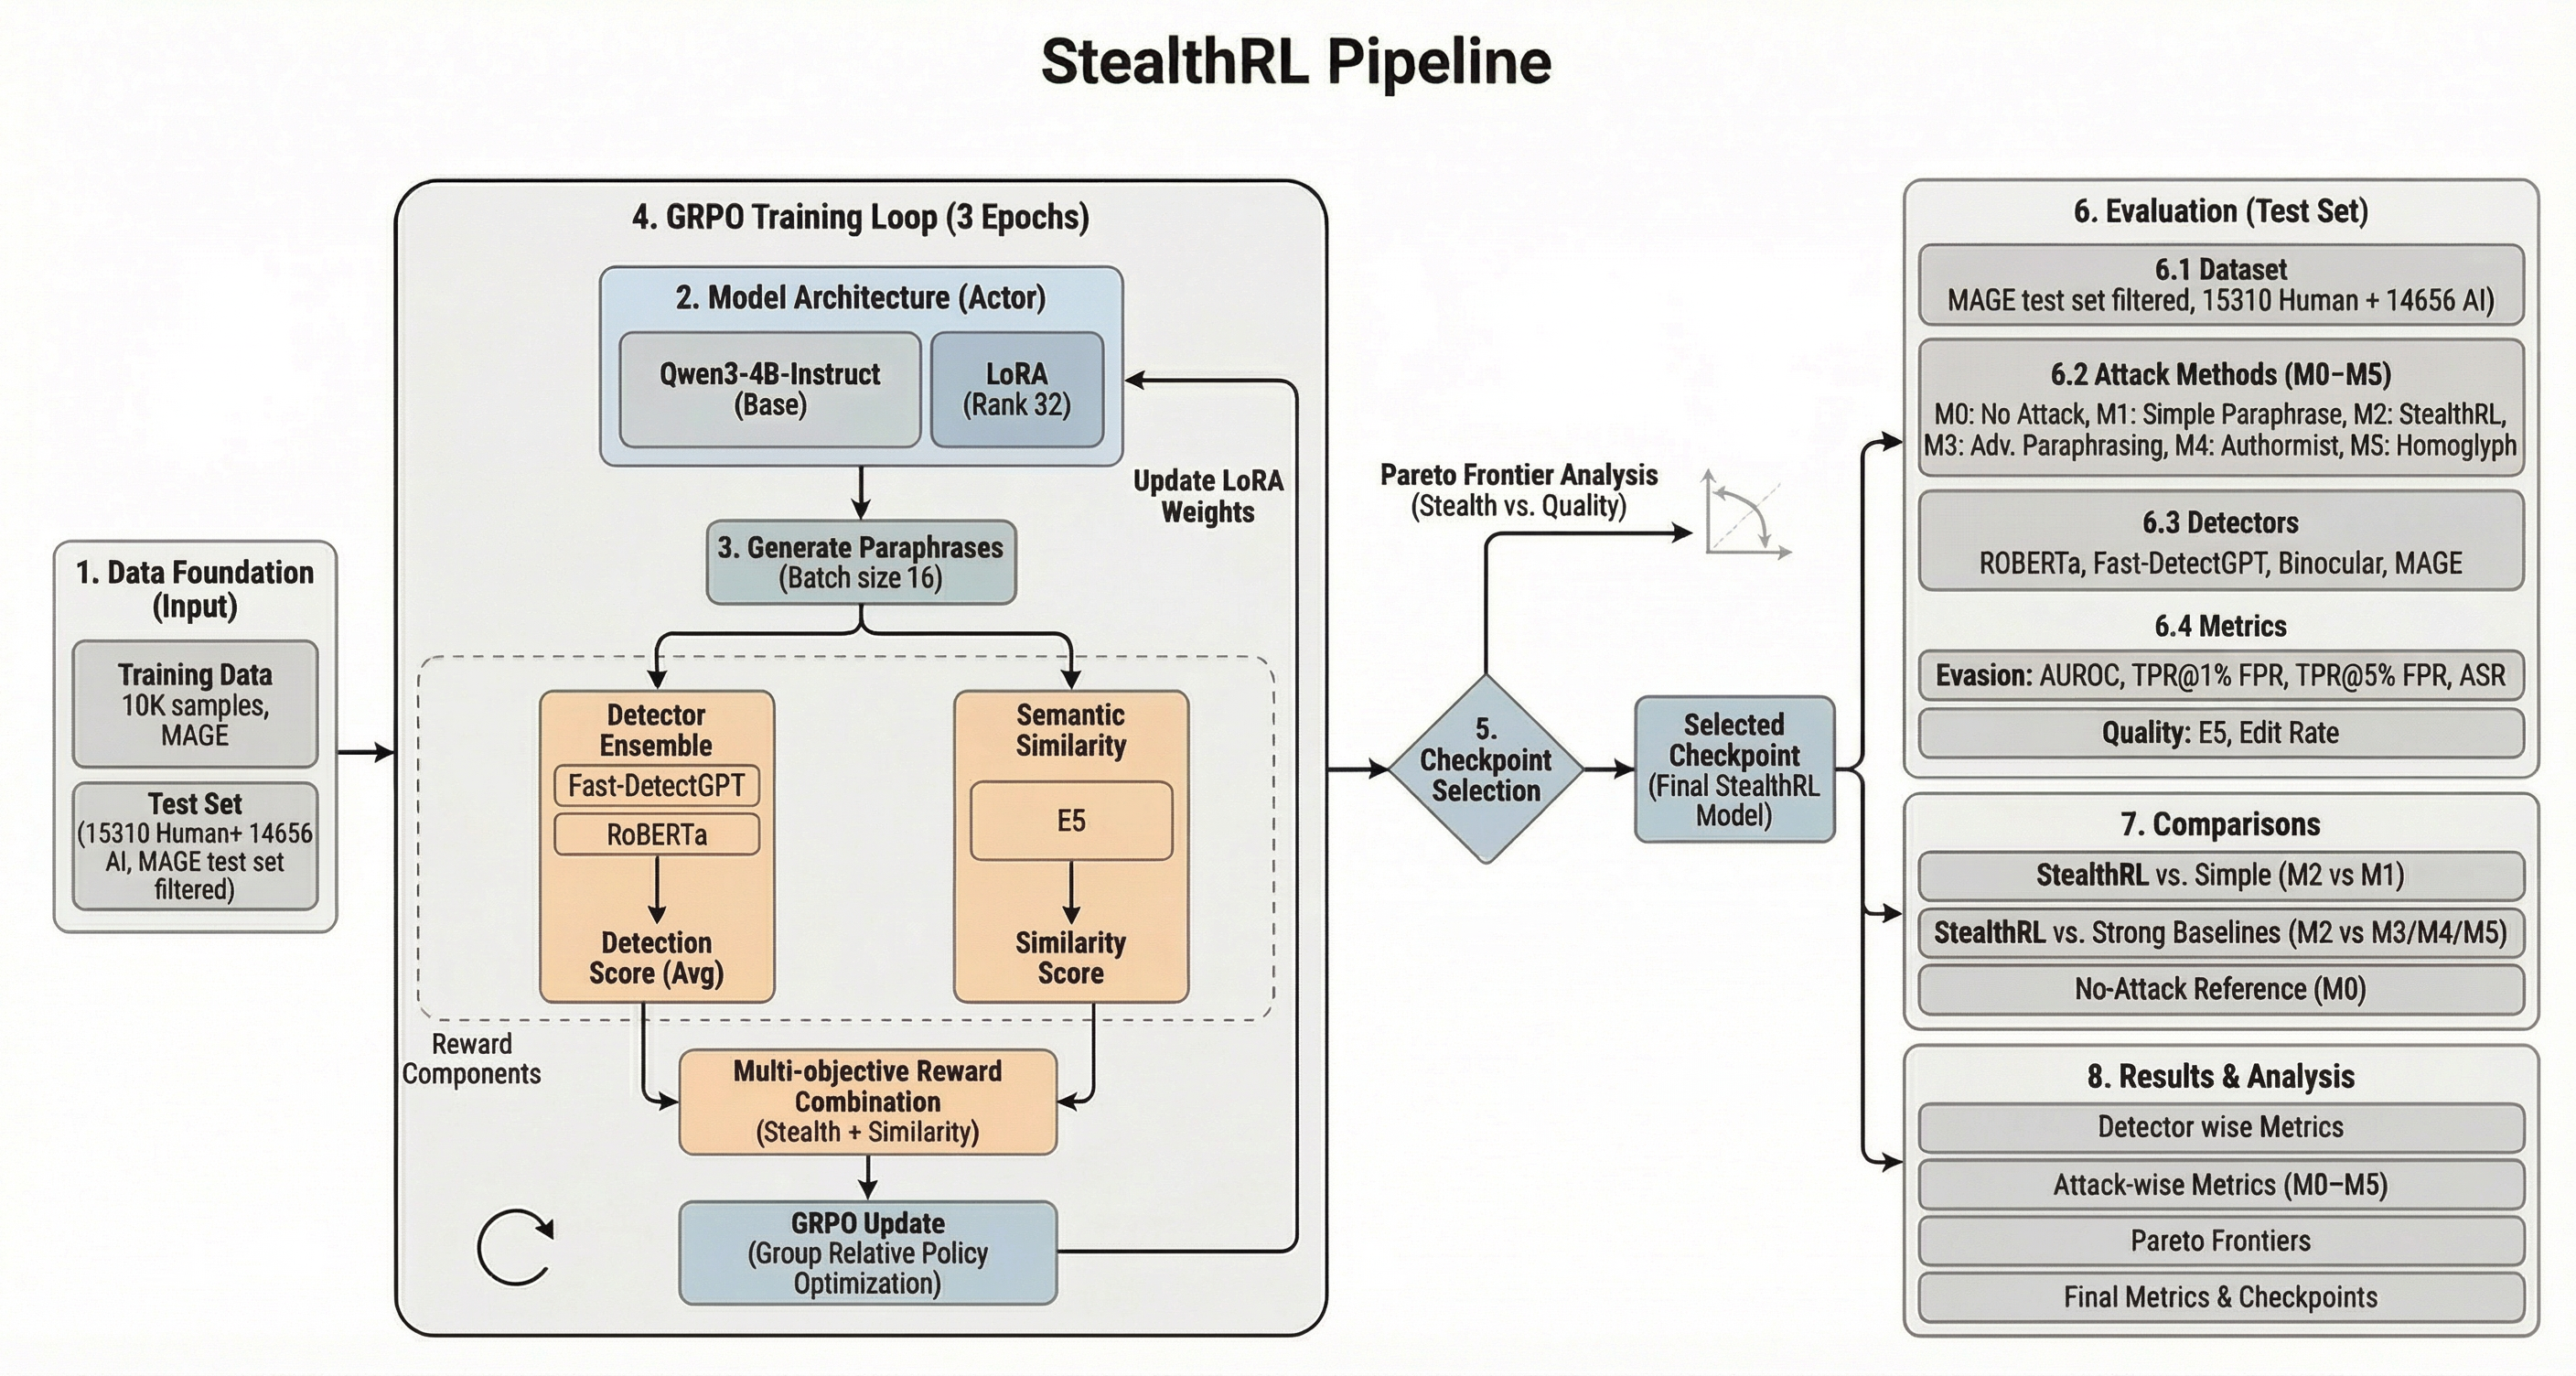
AI-text detectors are increasingly used in high-stakes settings, yet their robustness to meaning-preserving adversarial rewriting remains uncertain. We introduce StealthRL, a reinforcement learning framework for stress-testing AI-text detectors with adaptive paraphrase attacks. StealthRL trains a paraphrase policy against a detector ensemble while preserving semantic content, then evaluates transfer to held-out detector families. On the full filtered MAGE test pool (15,310 human / 14,656 AI), StealthRL reduces mean AUROC from 0.79 to 0.43 and achieves a 0.024 mean TPR@1%FPR across RoBERTa, Fast-DetectGPT, Binoculars, and MAGE. The attack transfers to two detectors not used during training, exposing shared vulnerabilities rather than a single-detector failure. We further analyze detector score distributions and evaluate quality with E5, BERTScore, and LLM-based Likert ratings. Our results show that current AI-text detectors remain brittle under realistic paraphrasing pressure and provide a reproducible protocol for adversarial robustness evaluation.
This repository is the research and engineering codebase behind StealthRL. It contains:
The repo is intended to be a useful starting point for researchers who want to:
stealthrl/: training code, detector wrappers, rewards, data utilities, and the original StealthBench packageeval/: research-grade evaluation harness used for the paper resultsscripts/: runnable entry points for training, evaluation, orchestration, plotting, and utilitiesconfigs/: YAML configs for training, evaluation, and ablationsfigures/: pipeline diagrams and static assetstests/: integration and sanity checksanalysis/: ad hoc analysis helpers and one-off utilitiespython -m venv venv
source venv/bin/activate
pip install --upgrade pip
pip install -r requirements.txt
Depending on which parts of the project you want to run, you may also need:
pip install tinker
pip install openai
pip install vllm
Notes:
tinker is required for the cloud-backed StealthRL checkpoint inference path used by M2.openai is only required for the GPT/Likert quality evaluation step.vllm is recommended for fast local generation in the paper baselines.Typical environment variables used by the repo:
export HF_HOME=$HOME/.cache/huggingface
export TRANSFORMERS_CACHE=$HF_HOME
export OPENAI_API_KEY=...
export TINKER_API_KEY=...
For the staged paper evaluation pipeline, we used an env file plus a checkpoint descriptor JSON. The public scripts let you override both paths explicitly:
python scripts/run_full_mage_research_eval.py \
  --env-file ~/.config/stealthrl/eval.env \
  --checkpoint-json ~/.config/stealthrl/m2_checkpoint.json
python scripts/run_eval.py --quick
python scripts/run_stealthbench.py --config configs/stealthbench.yaml
This now loads the configured text files, runs the configured detectors, saves CSV outputs, and generates comparison plots. The old TODO-only stub has been removed.
python scripts/run_full_mage_research_eval.py \
  --env-file ~/.config/stealthrl/eval.env \
  --checkpoint-json ~/.config/stealthrl/m2_checkpoint.json \
  --run-root outputs/eval_runs/full_mage_public \
  --gpus 0 1 2 3
The repository includes a FastAPI-backed demo website under demo/. It serves a polished static UI and exposes POST /api/paraphrase with API-key support plus a 20/day public quota for unauthenticated users.
pip install -r demo/requirements.txt
uvicorn demo.stealthrl_demo.app:app --reload --port 8080
By default the demo runs in zero-cost mock mode for UI testing. To use the real StealthRL sampler, set STEALTHRL_DEMO_INFERENCE_BACKEND=tinker, STEALTHRL_DEMO_CHECKPOINT_JSON, and TINKER_API_KEY. See demo/README.md for API-key, quota, Docker, and AWS deployment notes.
The paper reports results on the full filtered MAGE evaluation pool:
The research-grade evaluation pipeline is implemented in the eval/ module plus the staged scripts under scripts/.
Prepare credentials and checkpoint metadata.
Create an env file containing OPENAI_API_KEY and TINKER_API_KEY, and a checkpoint JSON describing the StealthRL Tinker sampler path.
Run preflight.
python scripts/preflight_research_eval.py \
  --env-file ~/.config/stealthrl/eval.env \
  --checkpoint-json ~/.config/stealthrl/m2_checkpoint.json
python scripts/run_full_mage_research_eval.py \
  --env-file ~/.config/stealthrl/eval.env \
  --checkpoint-json ~/.config/stealthrl/m2_checkpoint.json \
  --run-root outputs/eval_runs/full_mage_repro \
  --gpus 0 1 2 3
Inspect generated method outputs, detector scores, metrics, and plots under the chosen run directory.
If you only need to rerun GPT-based quality judging on cached outputs:
python scripts/run_gpt_quality_only.py \
  --run-root outputs/eval_runs/full_mage_repro \
  --env-file ~/.config/stealthrl/eval.env
python scripts/compute_bertscore_for_run.py \
  --run-dir outputs/eval_runs/full_mage_repro/assembled \
  --device cuda:0 \
  --batch-size 16 \
  --chunk-size 512
The BERTScore script updates quality.parquet and quality.csv in place after every chunk, so interrupted runs can be resumed without recomputing completed rows. Use --limit-per-method for a small smoke test and --force only when intentionally recomputing existing BERTScore columns.
The staged run produces:
method_runs/: per-method generated outputsdetector_scores/: per-detector parquet score filesassembled/metrics.json: aggregate detector metricsassembled/thresholds.json: calibrated detector thresholdsassembled/quality.parquet: automatic quality metricsassembled/quality_gpt.parquet: GPT/Likert quality ratingsassembled/figures/: paper-ready plots