 spiralbl0ck/learning-history-of-cff-bug-in-iphone
Dive into CFF font and coincidently learn about a bof in cff parsing from some jailbreak. just for fun

Dive into CFF font and coincidently learn about a bof in cff parsing from some jailbreak. just for fun
So.... wtf is CFF ? So from my knowledge it's a file format , but let's try to understad what wikipedia says:"CFF acts as a container to store multiple fonts together in a single unit known as a FontSet. "(https://docs.fileformat.com/font/cff/) so basically we can store fonts together . cool so now what ? well since it's a file format it has to have some spec, and yes it does have one and no it's not nice cause it's 60 pages and i am not willing to learn from it's format. But we can use the exploit from star-master github repo(source code from jailbreak 2.0 i think) in order to learn about it's format.
So... We start by using cff.py script provided by the author and we also open out.cff(standard simple .cff file) file in hxd editor.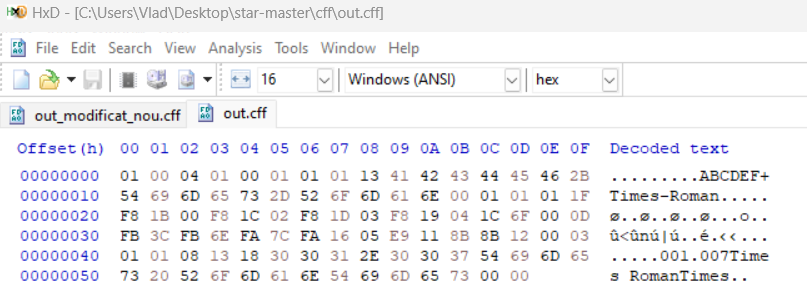
We can see that when we feed the file to the parse we get the folllowing
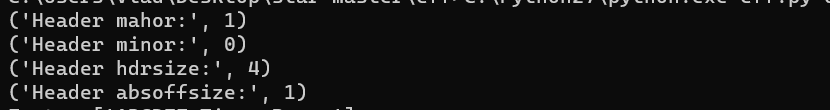
So we have already done some progress as we can already come with a definition for cff as we can come to the conclusion that we have some metadata about it's header which indicates the tff versions i presume, the headersize,and absoffsize whatever that might be.
So until now |major version(1 byte)|minor version(1 byte)|header size(1 byte) | header absoffsize(1 bytes) |
We than go further and have a function which get's what fonts are being used in this .cff file. As seen
So from where do we know that it's purpose is to read what fonts are being used ? Well upon running the tool we got the following result in cmd

which we see that are the next bytes after the metadata of the file

We will come back later to the analysis of this function later but for now we can deduce that the file format is |major version(1 byte)|minor version(1 byte)|header size(1 byte) | header absoffsize(1 bytes) | ABCDEF+fonts in pack|
Further we see that we search for what is called string in the script:
Why is that ? Because i presume that they want to gether info about the font used in the pack . From the docs, they say:"All the strings, with the exception of the FontName and CIDFontName strings which appear in the Name INDEX, used by different fonts within the FontSet are collected together into an INDEX structure and are referenced by a 2-byte unsigned number called a string identifier or SID.These strings, known as the standard strings, describe all the names used in the ISOAdobe and Expert character sets" . Anyways one interesting thing to note here is that we skipped roughly 41 bytes in order to get to the string.
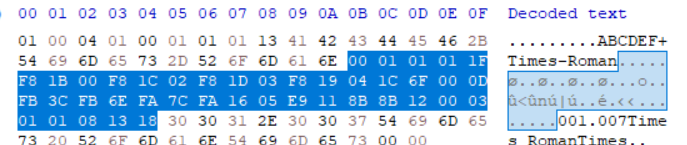

next we get information about the fonts present in the .cff file
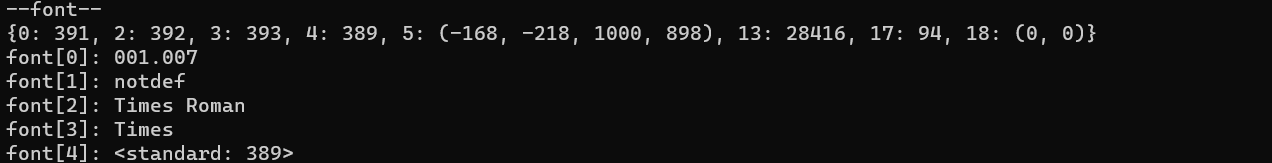
How tf do we do that ? well we gather what's called top dict data . wtf is that ? well from what i was able to understand from the docs, is a python dict with certain information in it , encoded in a certain way.
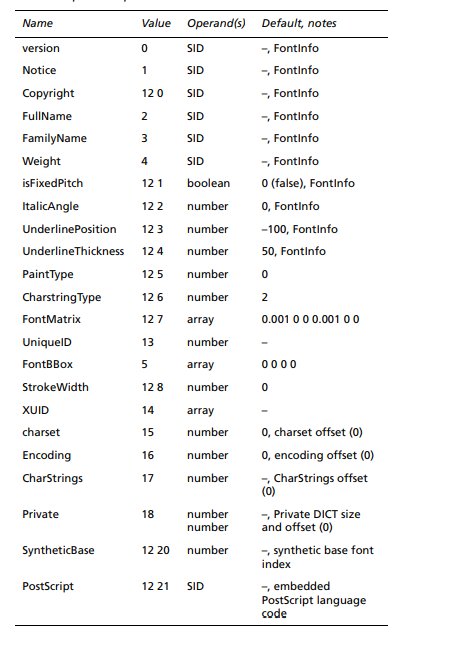
Coincidently, if we follow the decoding algo:
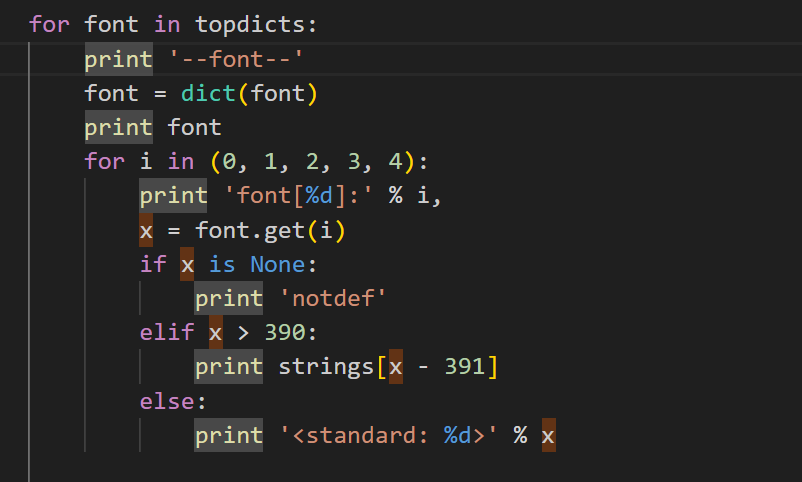
we dereference the strings data type to get info about the font, so we conclude that the topdicts simply has some indexes which later get used in strings data type to get info about font
So till now the definition of the file still stands,
|major version(1 byte)|minor version(1 byte)|header size(1 byte) | header absoffsize(1 bytes) | ABCDEF+fonts in pack|41 bytes known|25 bytes of info about font|
Cool so what happens next ? Well if we inspect the parser script we see that it gets,charstring_off,private_off and it will go to charstring_off position and read some more stuff
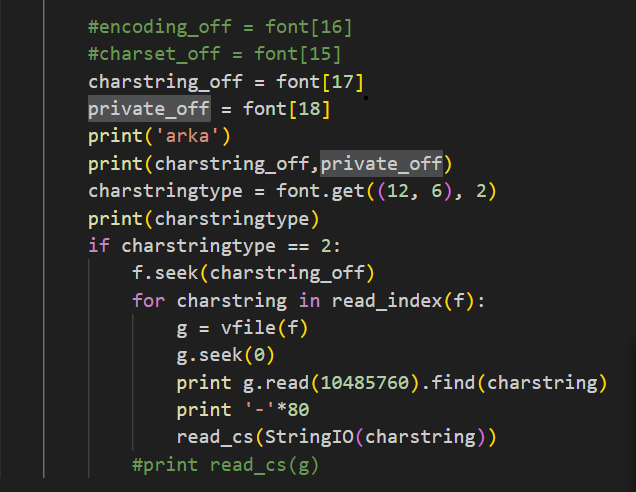
But how does it help us to make sense of bigger view. So i will abruptly conclude this. Basically i did a diff between 2 files, one normal cff and the corrupted cff.
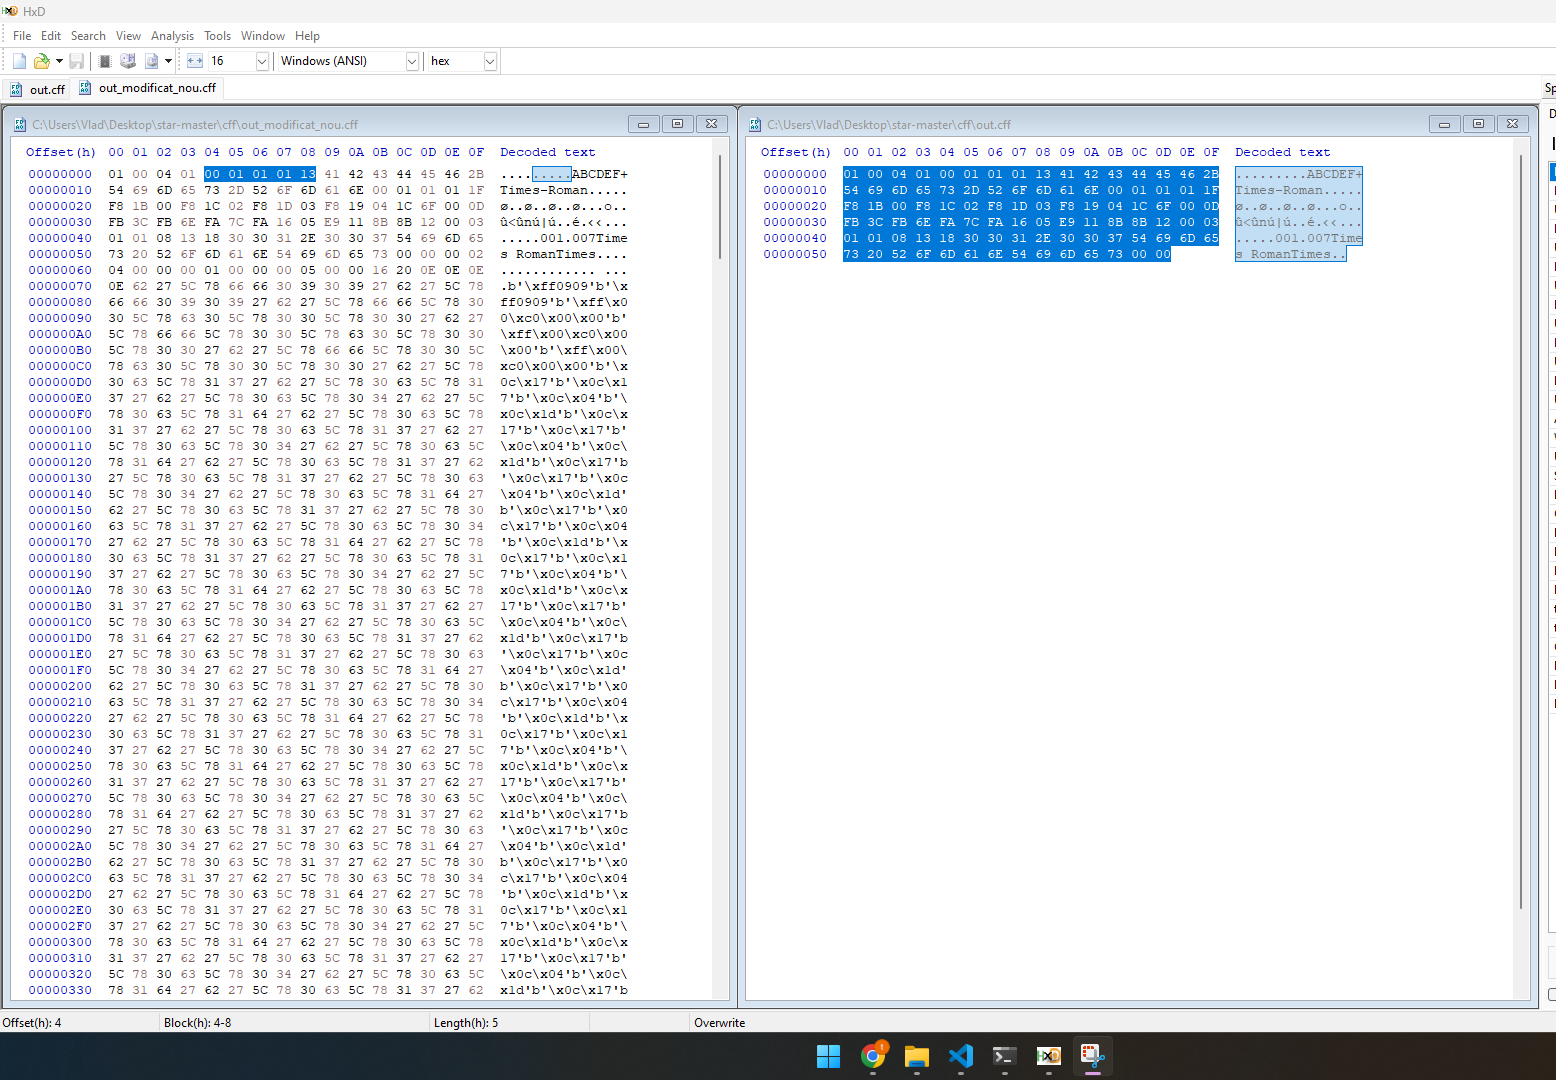
On left is the corrupted .cff file and on right is a normal .cff file. If we inspect the runtime result
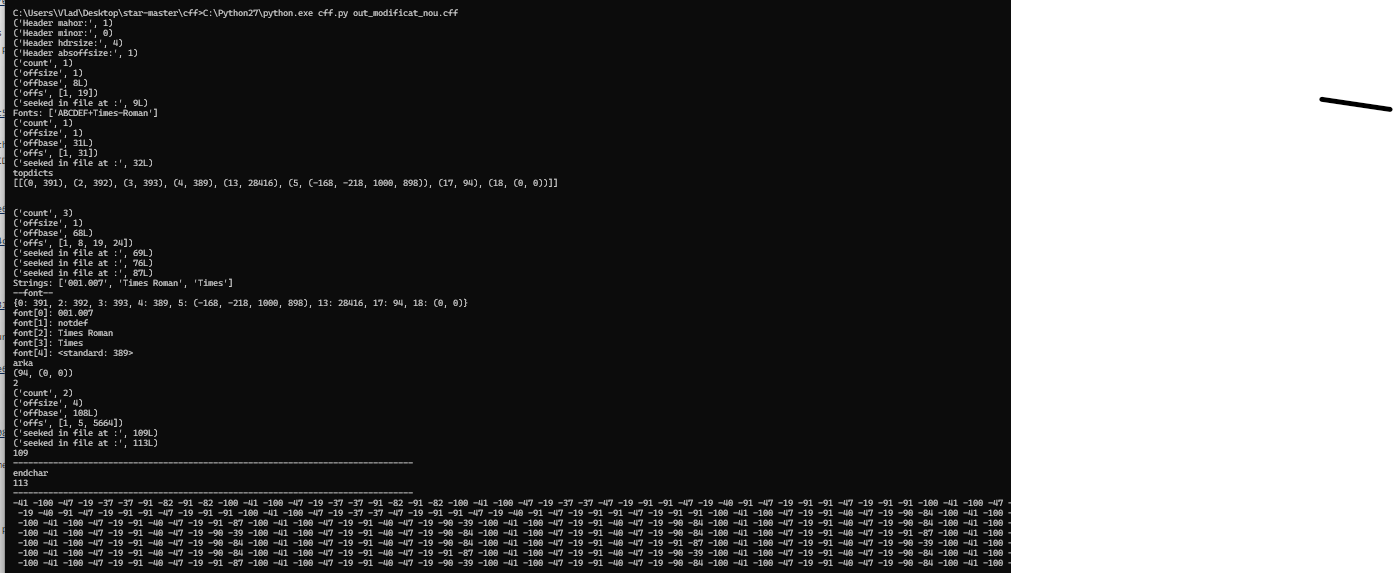
On first time when running the parse we see that everything such as count , offsize, offbase is simply some offsets till some delimters. What delimiters ? Precisly the name of font. So as you can see ('offbase', 8L) so from the start of the file till first encounter of the string of the font present in cff file
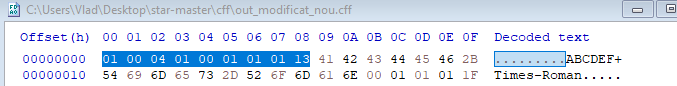
As can also be seen in "second run of parse"
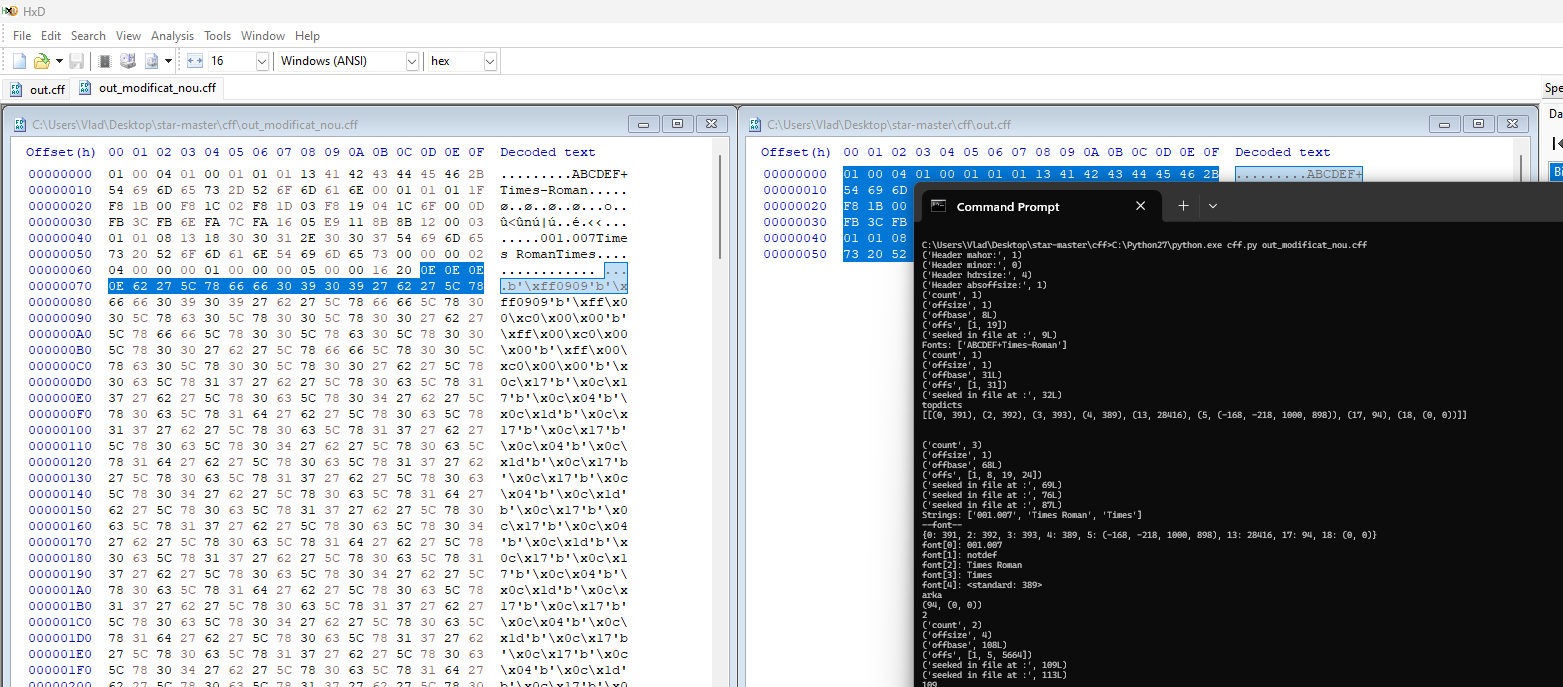
we see at 0x6c offset in hexviewr the \x0e\0xe\0xe\x0e beginning of out mallicous data
So as a conclusion a general format of .cff file format
|major version(1 byte)|minor version(1 byte)|header size(1 byte) | header absoffsize(1 bytes) | ABCDEF+fonts in pack|41 bytes known|25 bytes of info about font|
And custom file format(with user content)
|major version(1 byte)|minor version(1 byte)|header size(1 byte) | header absoffsize(1 bytes) | ABCDEF+fonts in pack|41 bytes uknown|25 bytes of info about font| 4 bytes(count) | 4 bytes(offsize) | 9 bytes left to be doccumented| user content|
