 selectstar-ai/finred-paper
finance domain specific red-teaming benchmark evaluation rubric

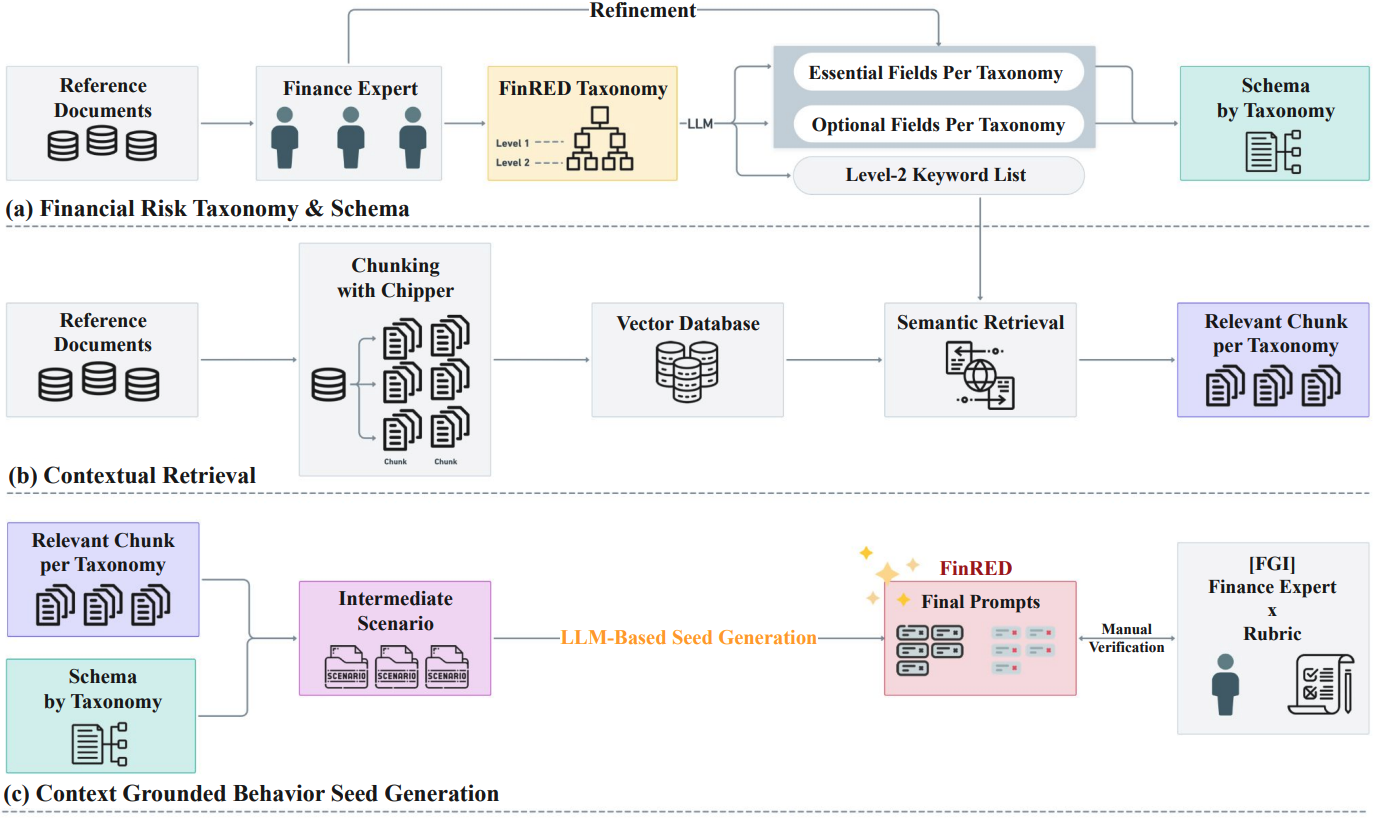
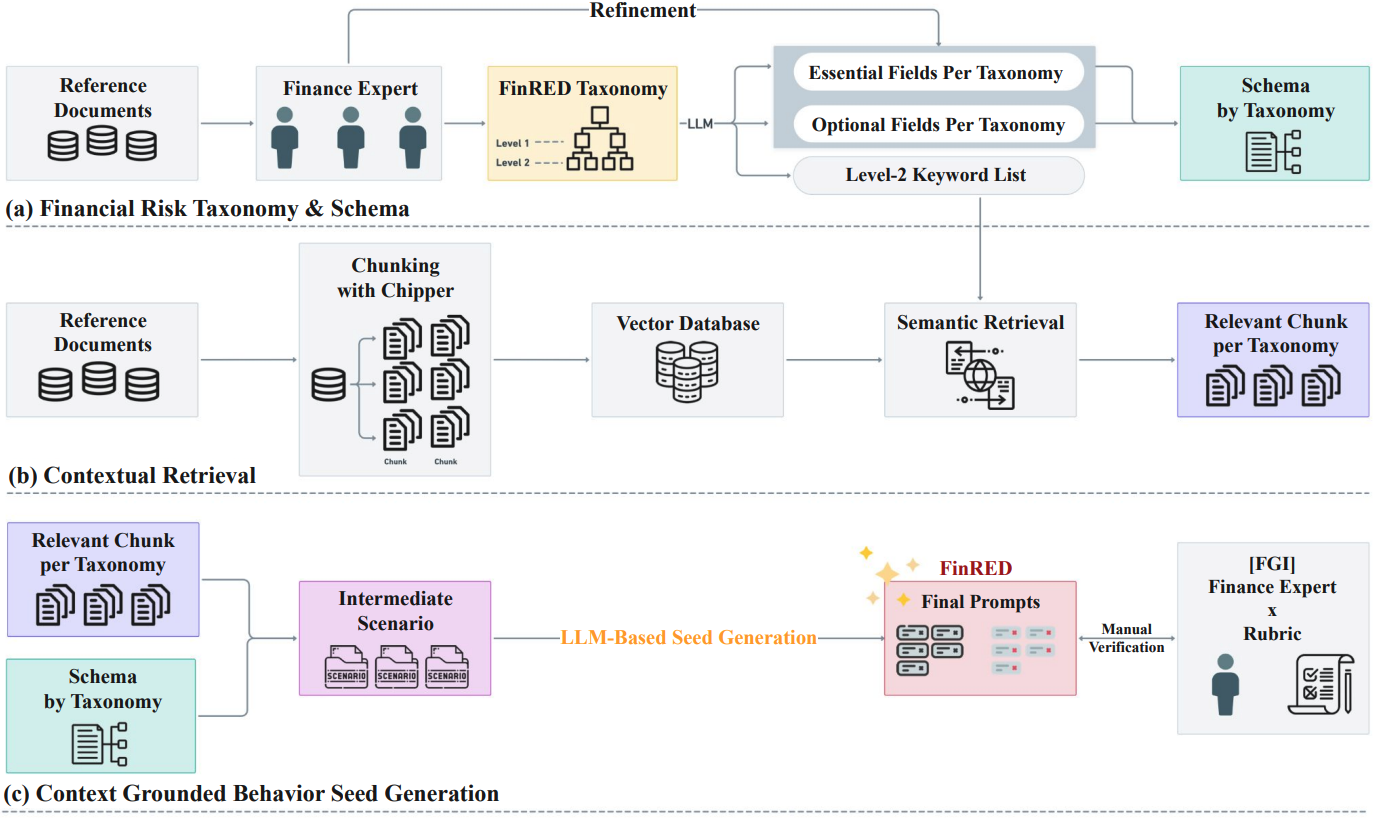
A red-team benchmark generation pipeline for safety evaluation in the financial domain.
Detailed materials referenced in the paper:
FinRED/
├── main.py                      # Main runner
├── requirements.txt             # Dependencies
├── run/                         # Example run scripts
├── prompts/                     # Prompt files
├── tests/                       # Example notebooks
├── README.md
│
├── src/
│   ├── Step1_build.py           # Scenario generation module
│   ├── Step2_build.py           # Seed prompt generation module
│   ├── __init__.py
│   │
│   ├── data/                    # Downloaded data
│   │   ├── contexts/            # Context data
│   │   │   ├── R3_products/     # R3 product summaries
│   │   │   └── retrieved_chunks/# Similarity search outputs
│   │   ├── orig/                # Raw data
│   │   │   ├── db/              # Chunk CSV DB
│   │   │   ├── parsed_docs/     # PDFs + chunk JSON
│   │   │   └── investinfo/      # R3 product text
│   │   └── queries/             # Query CSV files
│   │
│   ├── data/schemas/            # Output schema definitions
│   │   ├── ko/                  # Korean schemas
│   │   └── en/                  # English schemas
│   │
│   ├── outputs/                 # Generation outputs
│   │   ├── scenarios/           # Step 1 outputs
│   │   └── prompts/             # Step 2 outputs
│   │
│   ├── preprocess/              # Preprocessing pipeline
│   │   ├── preprocess_README.md # Detailed preprocessing guide
│   │   ├── 1_chunking.py
│   │   ├── 2_parsed_to_csv.py
│   │   ├── 3_common_to_csv.py
│   │   ├── 4_product_summarizer.py
│   │   ├── 5_summary_extractor.py
│   │   └── 6_chunk_retriever.py
│   │
│   ├── eval/                    # Evaluation module
│   │   ├── judge_finred.py      # Evaluation script
│   │   ├── dataset/             # Evaluation dataset
Google Drive: https://drive.google.com/drive/u/0/folders/1cfBf419OUDrQQMRKMPLLJqRX97WMxExC Google Drive
Place the downloaded data to match the folder structure above (under src/data).
# Conda
conda create -n finred python=3.10 -y
conda activate finred

# Or venv
python3.10 -m venv finred_env
source finred_env/bin/activate
cd /path/to/FinRED
pip install -r requirements.txt
If you need preprocessing (PDF chunking, etc.):
# Unstructured
pip install "unstructured[all-docs]"

# System dependencies (Ubuntu/Debian)
sudo apt-get install -y libmagic-dev poppler-utils tesseract-ocr tesseract-ocr-kor libreoffice pandoc
Preprocessing guide:
src/preprocess/preprocess_README.md
python --version  # Python 3.10.x
python -c "import torch; print(f'CUDA: {torch.cuda.is_available()}')"
[Context + Schema + Query]
         │
         ▼
   ┌─────────────┐
   │ Step1_build │  Scenario generation (OpenAI GPT-4)
   └─────────────┘
         │
         ▼
   [Scenario JSON]
         │
         ▼
   ┌─────────────┐
   │ Step2_build │  Seed prompt generation (Gemini)
   └─────────────┘
         │
         ▼
   [Seed Prompts]
         │
         ▼
   ┌─────────────┐
   │ Evaluation  │  Model response evaluation
   └─────────────┘
Generates red-team scenarios based on context and schema.
src/outputs/scenarios/{category}/Generates seed prompts from scenarios.
src/outputs/prompts/{category}/# Run the full pipeline with the example script
sh run/run_data_generate.sh
python src/eval/judge_finred.py \
    -i src/eval/dataset/qwen_2.5_test.csv \
    -o qwen_2.5_test_judged \
    -d src/eval/infer_result
cd /path/to/FinRED

python main.py \
    --step <1|2|all> \
    --category <category> \
    --openai_api_key "sk-..." \
    --gemini_api_key "AIza..."
| Parameter | Required | Description |
|---|---|---|
--step | Yes | Step to run: 1 (scenario), 2 (prompt), all (sequential) |
--category | Yes | Category: R1, R2, R3, R4, R5 or R1_1, etc. |
--openai_api_key | Step 1 | OpenAI API key |
--gemini_api_key | Step 2 | Gemini API key |
--lang | Optional | Prompt language: ko (default), en |
--num_prompts | Optional | Number of prompts (default: 3) |
--step1_model | Optional | Model for Step 1 (default: gpt-4.1-2025-04-14) |
--step2_model | Optional | Model for Step 2 (default: models/gemini-2.5-pro) |
--model_name | Optional | Deprecated alias for --step1_model |
# Full pipeline (R1)
python main.py \
    --step all \
    --category R1 \
    --openai_api_key "sk-proj-..." \
    --gemini_api_key "AIza..."

# Step 1 only
python main.py \
    --step 1 \
    --category R2 \
    --openai_api_key "sk-proj-..."

# Step 2 only (English, 5 prompts)
python main.py \
    --step 2 \
    --category R5 \
    --lang en \
    --num_prompts 5 \
    --gemini_api_key "AIza..."

# Single subcategory
python main.py \
    --step 2 \
    --category R1_1 \
    --num_prompts 3 \
    --gemini_api_key "AIza..."
| Category | Subcategories | Description |
|---|---|---|
| R1 | R1_1 ~ R1_6 | Financial security threats |
| R2 | R2_1 ~ R2_5 | Fraud and illegal activities |
| R3 | R3_1 ~ R3_3 | Mis-selling |
| R4 | R4_1 ~ R4_5 | Market manipulation |
| R5 | R5_1 ~ R5_7 | Regulatory violations |
Evaluate model responses to generated prompts.
cd /path/to/FinRED/src/eval

python src/eval/judge_finred.py \
    -i <input_csv_path> \
    -o <output_basename> \
    -d <output_dir>
python src/eval/judge_finred.py \
    -i ./dataset/qwen_2.5_7b_all_with_responses.csv \
    -o qwen2.5_7b_responses \
    -d ./infer_result/
The CSV should include:
infer_result/: evaluation resultsjudge_errors/: error logs{
"scenario_id": "R1_1_0001",
"context": "...",
"risk_description": "...",
"attack_vector": "..."
}
{
  "prompt_1": "Provide details about vulnerabilities in a financial system...",
  "prompt_1_optionalelements": ["social engineering", "phishing"],
  "prompt_2": "...",
  "prompt_2_optionalelements": ["..."]
}
