
Skip to content
KitploitKITPLOIT
ToolsExploitsBlog
Log in
Submit
ToolsExploitsBlog
Submit

Hacking, PenTest, and Cybersecurity Tools for Your Security Arsenal!

Kitploit is a directory of hacking, cybersecurity, and pentesting tools. Discover the latest project updates to find vulnerabilities, analyze systems, automate testing, and strengthen your security.

··Feeds·Contact·Privacy·© 2026 Kitploit

Tool Directory

Categories

View all categories
Loading categories
oss-fuzz-gen — LLM powered fuzzing via OSS-Fuzz. | Kitploit
Tools/GitHubGitHub/google/oss-fuzz-gen
Vulnerability AnalysisDynamic Code Analysis (DAST)FuzzingDevSecOpsMachine LearningAI Security
GitHubgoogle/oss-fuzz-gen

oss-fuzz-gen

LLM powered fuzzing via OSS-Fuzz.

View Repository
1.4k224367 months agoReviewed by Kitploit

Most Popular

View all →

Discover the most used tools by our community.

Explore all tools

Browse our collection of tools

View all tools →
Share

A Framework for Fuzz Target Generation and Evaluation

This framework generates fuzz targets for real-world C/C++/Java/Python projects with various Large Language Models (LLM) and benchmarks them via the OSS-Fuzz platform.

More details available in AI-Powered Fuzzing: Breaking the Bug Hunting Barrier: Alt text

Current supported models are:

  • Vertex AI code-bison
  • Vertex AI code-bison-32k
  • Gemini Pro
  • Gemini Ultra
  • Gemini Experimental
  • Gemini 1.5
  • OpenAI GPT-3.5-turbo
  • OpenAI GPT-4
  • OpenAI GPT-4o
  • OpenAI GPT-4o-mini
  • OpenAI GPT-4-turbo
  • OpenAI GPT-3.5-turbo (Azure)
  • OpenAI GPT-4 (Azure)
  • OpenAI GPT-4o (Azure)

Generated fuzz targets are evaluated with four metrics against the most up-to-date data from production environment:

  • Compilability
  • Runtime crashes
  • Runtime coverage
  • Runtime line coverage diff against existing human-written fuzz targets in OSS-Fuzz.

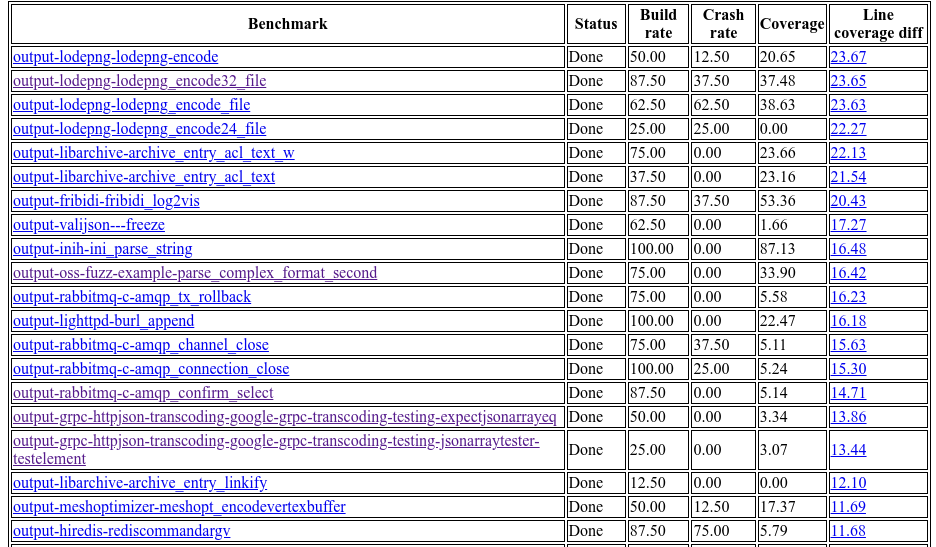
Here is a sample experiment result from 2024 Jan 31. The experiment included 1300+ benchmarks from 297 open-source projects.
image

Overall, this framework manages to successfully leverage LLMs to generate valid fuzz targets (which generate non-zero coverage increase) for 160 C/C++ projects. The maximum line coverage increase is 29% from the existing human-written targets.

Note that these reports are not public as they may contain undisclosed vulnerabilities.

Usage

Check our detailed usage guide for instructions on how to run this framework and generate reports based on the results.

Independent Agent Execution and Evaluation

You can also execute or evaluate individual agents without running full experiments, using the integrated agent execution framework. See the framework's documentation for detailed instructions on how to run individual agents or sequence of agents.

Collaborations

Interested in research or open-source community collaborations? Please feel free to create an issue or email us: [email protected].

Bugs Discovered

Download Tool