
 0xsteph/pentest-ai
Open-source AI pentester that proves every finding. Machine oracles re-run each exploit; verified bugs ship a proof capsule you can replay yourself.
It doesn't flag. It proves.


Website · Install · Why verification · Benchmarks · Limits · Discord
⚠️ Offensive tooling, authorized testing only. By installing you accept the AUP and Terms. See Responsible use ↓
pip install ptai && ptai demo
ptai demo scans a bundled vulnerable app and prints 4 findings, 3 oracle-VERIFIED.
It replays one live from a proof capsule (replay 3/3), then runs the same routes
hardened and prints 0 findings.
Two things to notice. The findings appear and disappear with the vulnerability rather than because the tool went quiet — the only thing that changed between the two runs is the fix. And one of the four stays a candidate: the SQLi login bypass is real, but no oracle could re-prove it on that route, so it does not get a badge. That gap is the product working, not a bug in the demo.
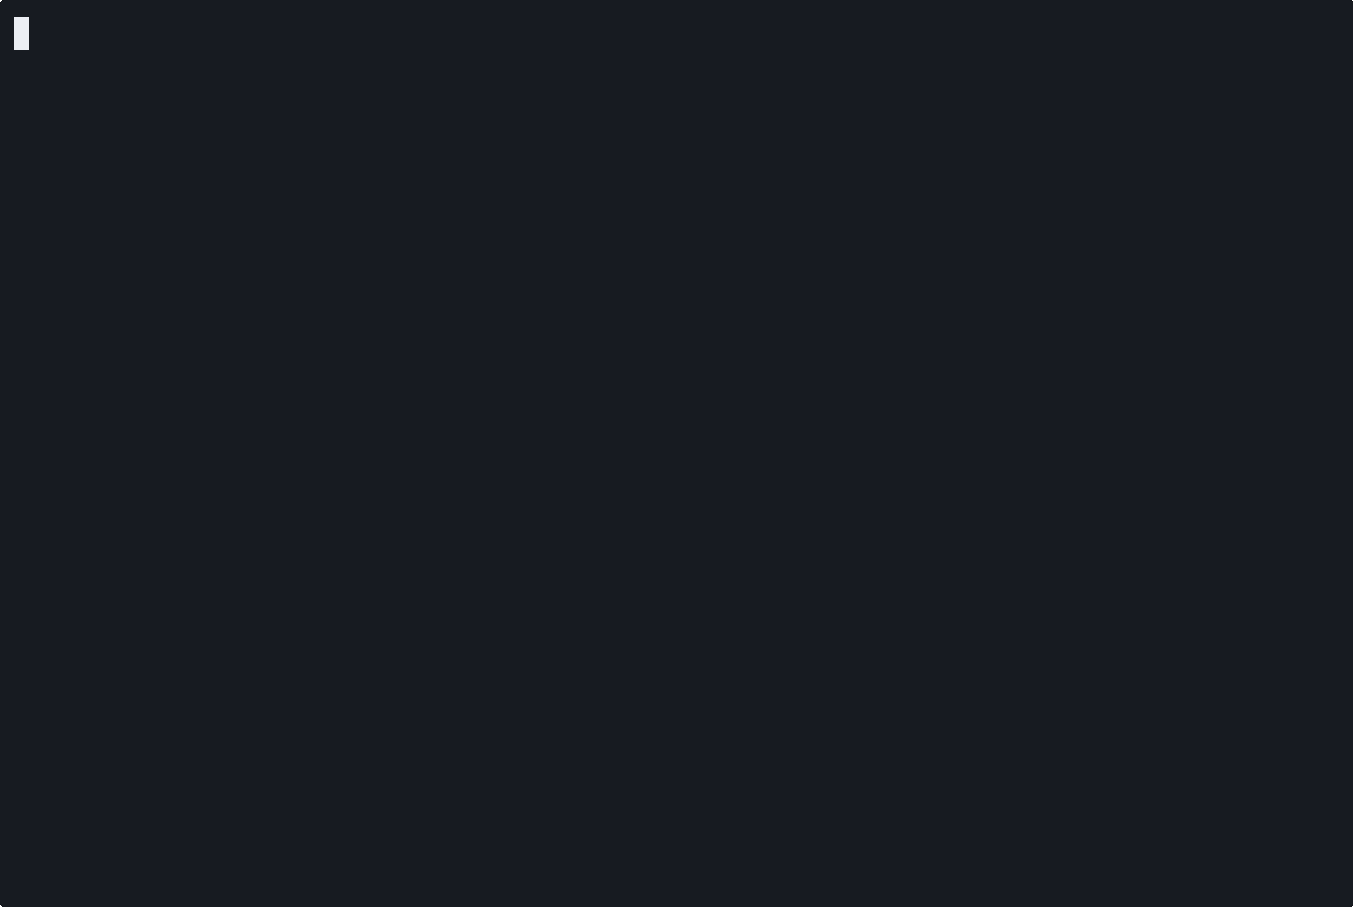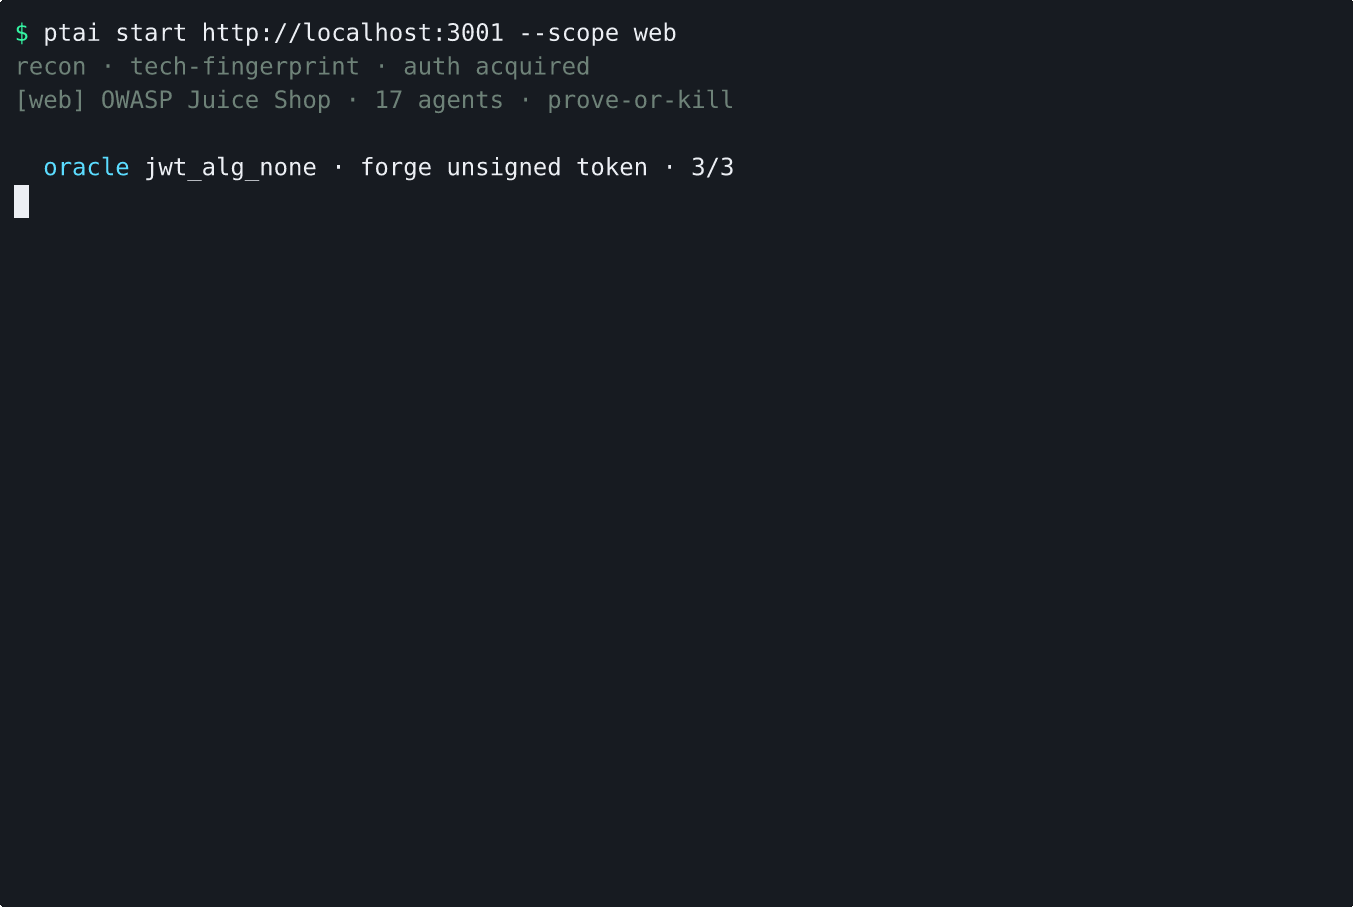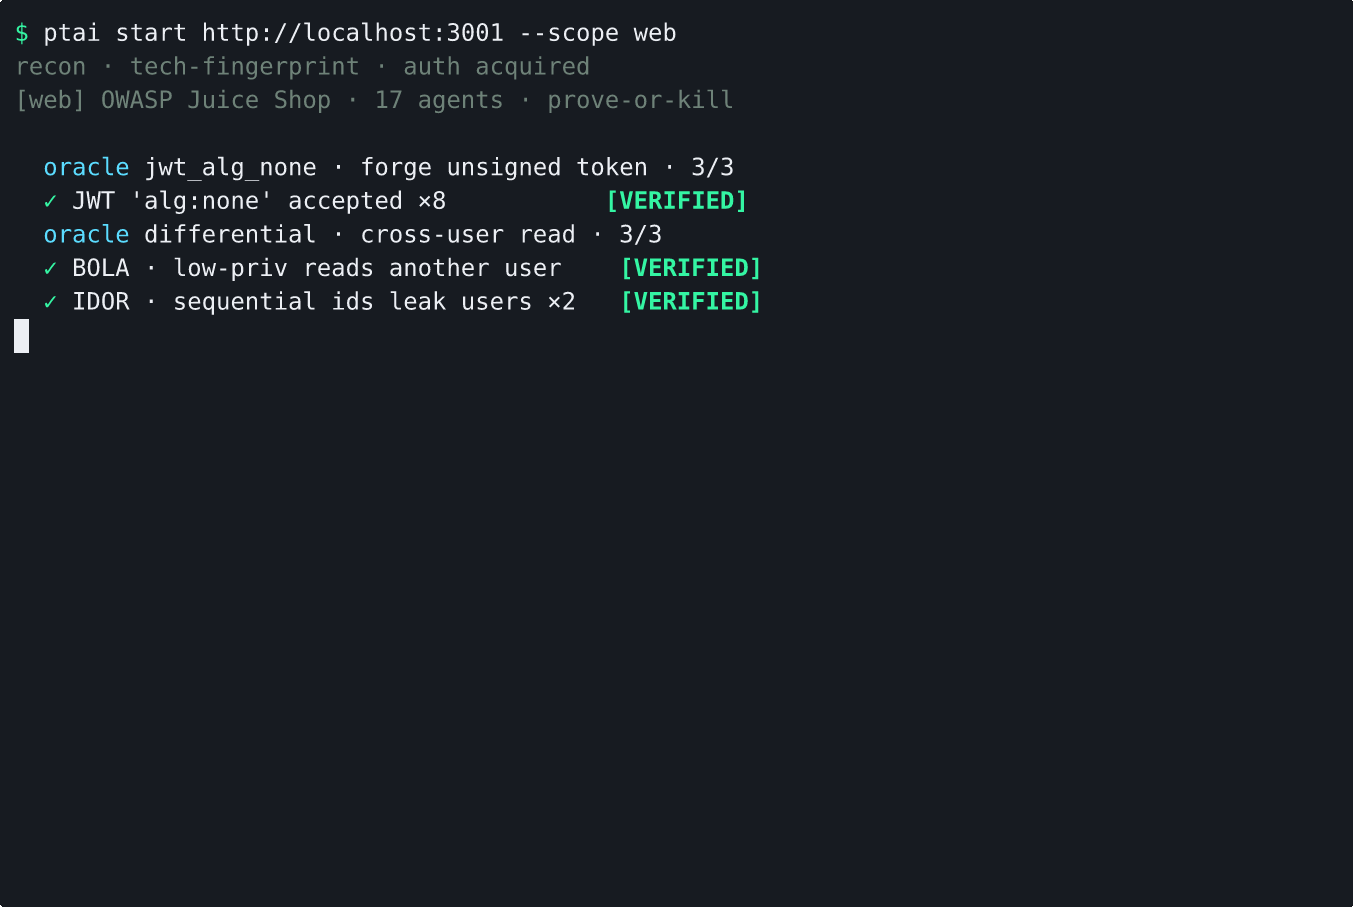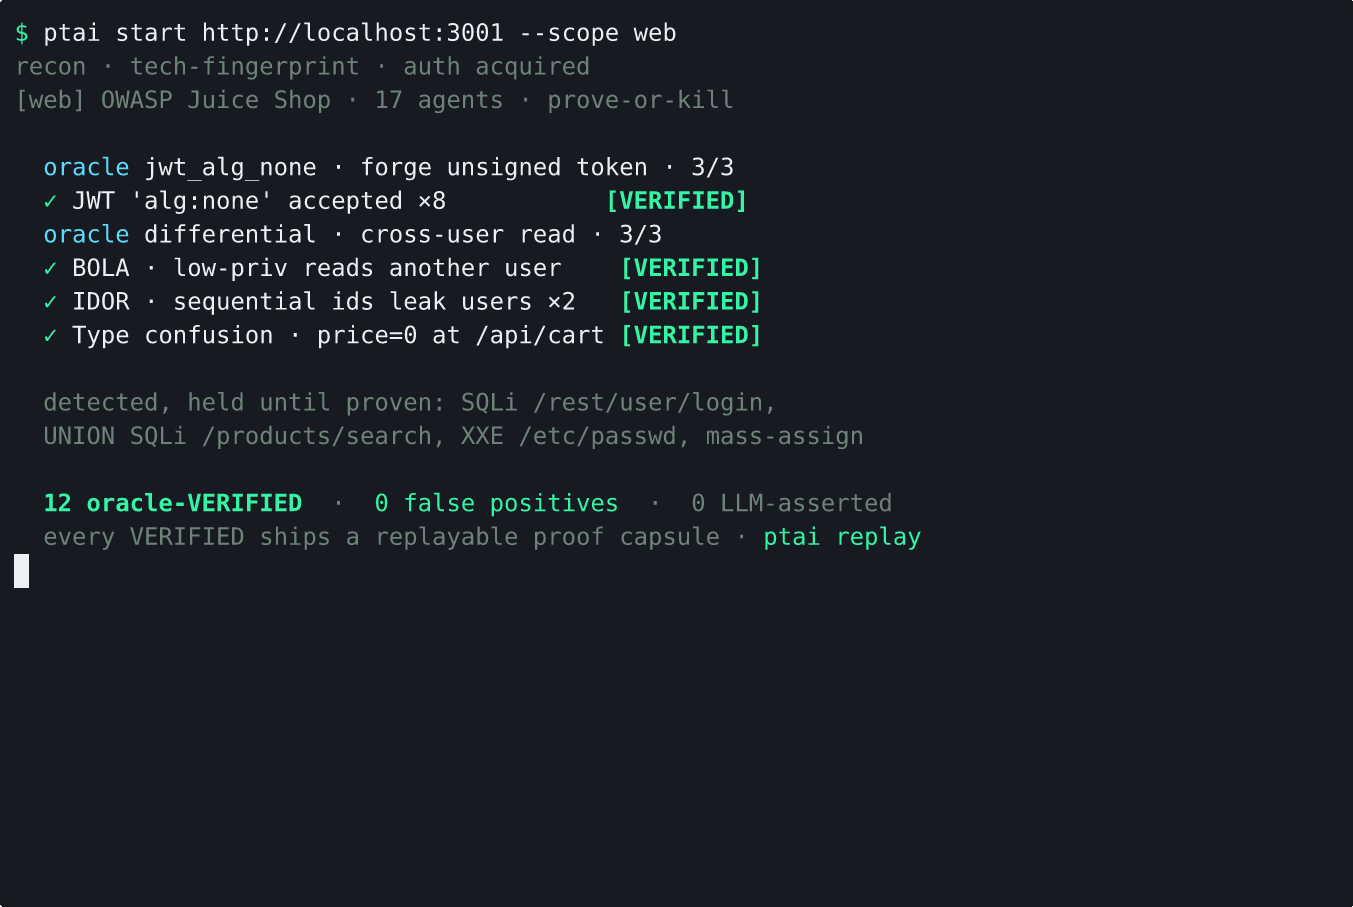
Most scanners tell you a thing might be exploitable and leave the triage to you. ptai treats a finding as a candidate until a named machine oracle re-runs the exploit and reproduces it N out of N times. Only then does it earn VERIFIED.
Three properties make that more than a slogan:
No LLM ever produces a verdict. The rule is enforced in code, not by policy: a verdict that cannot name the oracle that earned it is rejected. An LLM coordinates the run and reasons about results. It never decides whether a bug is real.
Every oracle has a control that must fail. A trusted-header bypass has to return privileged content with the header and a denial without it. A leaked-credential check has to be accepted for the real secret and rejected for a deliberately corrupted twin. An endpoint that answers 200 to everything earns nothing. This is what stops "it returned 200" from being mistaken for proof.
Third-party scanner output is held back. nuclei, nikto and zap results do not become findings on their own authority. They stay unverified until one of ptai's own oracles re-proves them independently.
Each VERIFIED finding ships as a portable proof capsule — the finding, the
recipe to re-prove it, and the receipt. Anyone can ptai replay it against the
live target and watch the oracle re-confirm, without trusting ptai. Capsules are
deliberately unsigned: replay is the trust mechanism, not a signature you have to
take on faith.
| Vulnerability classes with a working oracle | 14 |
| Probes in the library | 64 |
| Probes that can earn VERIFIED | 30 |
| Oracle kinds | 24 |
| Tool wrappers | 203 |
| …that parse output into findings today | 18 |
| MCP tools | 52 |
| Specialist agents | 18 |
| Tests | 2,729 on Python 3.10 / 3.12 / 3.14 |
On a deliberately vulnerable honeypot, 23 findings verify across those 14 classes
at 100% precision with zero false positives. On a stock OWASP Juice Shop, 17
findings verified in the 2026-08-23 sweep — report in-scope HTTP / verified /
precision, not 17/116. A 2026-08-25 Path 1 MCP session (MCP client driving
run_probe, target died before orchestrator verify) earned 12 verified proofs
at 100% precision against 64 in-scope HTTP challenges (20 will-not-chase). OSINT,
Web3, and UI-only Juice Shop keys are out of the automation scoreboard by design.
Read those numbers carefully, because the gaps are the point. 64 probes exist but only 30 can earn a verdict; the other 34 report honest candidates. 203 wrappers are registered but only 18 turn tool output into findings — the rest run and hand back raw text. The oracle gate buys precision, not catch rate: it removes false positives, it does not find more bugs.
The honeypot harness (tests/honeypot/) and a clean-app
zero-false-positive gate (tests/cleanapp/) both ship in this
repo and run in CI, so these are reproducible rather than screenshots.
Stated plainly, because a security tool that oversells itself is worse than useless.
unsupported rather than a misleading zero.ptai playbook run resolves dependencies
and prints the plan. Running it against a target is not wired up yet.The complete internal defect list, including everything above, is tracked openly rather than quietly. If something here is wrong, open an issue and it gets corrected.
Your existing AI subscription is the LLM. ptai supplies the tools.
pip install ptai
ptai mcp install          # auto-detects your MCP clients and writes their configs
Restart the client and 52 tools are there. No Anthropic key needed on this path — the MCP server hosts no LLM of its own by design.
pip install ptai
export ANTHROPIC_API_KEY=sk-...        # or OPENAI_API_KEY
ptai start https://target.example.com

# fully local, no cloud:
export PENTEST_AI_LLM_PROVIDER=ollama

# or deterministic, no LLM at all:
ptai start https://target.example.com --no-llm
Spend is capped at $10 per engagement by default (PTAI_PRICE_LIMIT).

